


 Key Takeaways
Initial load is the very first transfer of all historical data from a source to a destination, whereas full load recopies the entire dataset and overwrites the existing information in the destination during every run, regardless of whether the data has changed.
- Frequency: Initial load happens only once, when data is first loaded into the destination. Full load can run repeatedly based on the configured schedule.
- Target state: Initial load populates an empty destination table with the source’s historical data. Full load replaces the existing destination data with a complete copy from the source.
- Complexity: Initial load requires setting up the baseline schema and preparing to handle potentially massive volumes of legacy data. Full load does not require setting up a new baseline schema, but it can still involve processing massive volumes of data on every run.
Initial load is typically used when setting up a new data warehouse or migrating data to a database or data warehouse for the first time. Full load is primarily used for small reference or lookup tables where tracking changes is harder than reloading the entire dataset.
Initial load and full load represent two foundational ways to move data during the ETL process, from a source to a destination. While both copy entire datasets, they serve entirely different purposes in a data pipeline’s lifecycle.
An initial load is a one-time event that populates an empty target destination with historical data. Think of it like moving into a brand-new house: you pack up everything you own and move it from your old house to the new one.
A full load, also called a full refresh, is a recurring process where the entire dataset is completely overwritten every time the pipeline runs. It’s similar to a restaurant menu board: instead of erasing and changing individual items, the restaurant clears the entire board and rewrites the complete menu from scratch.
In this guide, we’ll provide a detailed overview and comparison of initial load vs full load, including how they differ, when to use each approach and the considerations involved in choosing between them.
Table of Contents
Overview of Initial Load vs Full Load ETL
| Aspect | Initial Load | Full Load |
| Definition | The first instance of loading data into a target system from a source. It involves migrating all existing data for the first time. | A subsequent complete data load where all the data (old and new) is transferred from the source to the target system, regardless of previous loads. |
| Use Cases | – Setting up a new database or data warehouse.- Migrating legacy data to a new system for the first time. | – Periodic complete refresh of the target system.- When data in the target system becomes corrupted and needs a fresh copy. |
| Benefits | – Ensures that all historical data is captured and transferred at once.- One-time effort to initialize the system with data. | – Guarantees that the target system has the most up-to-date and complete data.- Ensures consistency and data integrity by refreshing all data. |
| Drawbacks | – May require system downtime during the process.- Data transfer failures can result in incomplete migration. | – May cause higher system downtime due to the size and scope of the operation.- Not efficient if only a portion of the data has changed (since all data is reloaded). |
| Frequency | Typically performed once, during the initial setup or system deployment. | Performed periodically (weekly, monthly, etc.), depending on the system’s need for complete data refresh. |
| Data Transfer | Only the existing historical data at the time of loading is transferred. | Transfers all data, including both existing and newly updated data, regardless of previous loads. |
| Example | Migrating customer data from an old CRM system to a new one. | Reloading all customer data into a CRM system after it was corrupted. |
What is Initial Load in ETL?
In the first instance, data gets loaded into the Data Warehouse for the first time. This is referred to as an Initial Load. To prevent running into out-of-memory exceptions due to the lengthy data loading process, you need to control how much data is loaded. To load the data, you need to first prepare it and test it in a production-like environment. The required capacity needs to be prepared to produce. Therefore, it becomes imperative to schedule production downtime for an initial load.
In ETL, Initial Load refers to history tables and transaction tables that are loaded into these data flows. The performance of ETL processes can be vastly improved by setting properties such as load intervals and filters.
Once the initial data load has occurred for a base object, any subsequent load processes are known as incremental loads because for this loading process, only updated or new data is loaded into the base object, and duplicate data gets ignored.
Looking for the best ETL tool in the market? Migrating your data can become seamless with Hevo’s no-code intuitive platform. With Hevo, you can:
- Automate Data Extraction: Effortlessly pull data from Shopify(and other 60+ free sources).
- Transform Data effortlessly: Use Hevo’s drag-and-drop feature to transform data with just a few clicks.
- Seamless Data Loading: Quickly load your transformed data into your desired destinations, such as BigQuery.
Try Hevo and join a growing community of 2000+ data professionals who rely on us for seamless and efficient migrations.
Get Started with Hevo for FreeWhat is ETL Full Load?
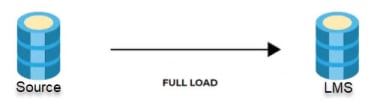
In a Full Data Load, the complete dataset is emptied or loaded and then entirely overwritten (i.e. deleted and replaced) with the newly updated dataset in the next data loading run. While comparing the Incremental Data Load vs Full Load, you also don’t need to maintain extra information such as timestamps to carry out a Full Data Load.
You can consider a simple example of a Shopping Mall that loads all of the total daily sales via the ETL process into a Data Warehouse at the end of each day. Assume that there were 1000 sales done on Monday, thus, you would need to load data on Monday night with a dataset of 1000 records.
Then, on Tuesday 700 more sales were done and need to be added. Similarly, on Tuesday night, 1000 Monday records, as well as 700 Tuesday records, will now be dumped in the Data Warehouse via the Full Load method.
Key Benefits of ETL Full Load
A Full Data Load is a traditional Data Loading method that offers the following benefits:
- Easy-to-Implement: When comparing the Initial Load vs Full Load ETL, executing a Full Data Load is a straightforward process that simply deletes the whole old table and replaces it with an entire updated dataset.
- Simple Design: Based on a particularly easy-to-set uploading process, a Full Data load doesn’t require you to worry about database design and keeping it clean. While comparing Initial Load vs Full Load ETL, you will notice that If an error occurs in a Full Load, you can simply re-run the loading process without having to do much else in the way of data cleanup/preparation.
- Low Maintenance: This technique doesn’t require you to manage the keys and whether some data is up to date or not as every time you reload the table, all data will be updated no matter what. For instance, when comparing the Initial Load vs Full Load ETL, dtime_updated, and dtime_inserted are the most commonly used keys in delta load.
Challenges of Full Data Load
While applying the Full Data Load approach, you may encounter the following ETL challenges:
- Unsustainable: It can be an inconvenient data-loading method when you only need to update just a handful of records but have to insert millions of records due to its ETL architecture.
- Slow Performance: As you start dealing with massive volumes of data, performing a full data load with a larger dataset is time-consuming and takes up a lot of server resources.
- Unable to Preserve History: With Full Data Load, you can’t keep the historical data as it drops the old data and the new dataset completely replaces it. This old data is often important as in some cases you may want to track the changes in the database.
Understanding the Differences between Initial Load and Full Load ETL
Initial Load vs Full Load ETL: Difficulty
The main difficulty of an initial load lies in setting up the schemas and pipeline before the first data transfer. Once the setup is complete, the initial load runs as a one-time baseline operation, so there is little ongoing effort.
A full load ETL, on the other hand, is easier to build because the required schemas and pipeline are already in place. However, running a full load becomes increasingly difficult over time. As the dataset grows, each run processes more data, takes longer, consumes more compute resources, increases costs, and can eventually put additional strain on the system.
Initial Load vs Full Load ETL: Time
The time required for both initial and full loads depends largely on the amount of data being processed.
An initial load can take longer when the source contains a large volume of historical data because the entire dataset must be loaded for the first time. A full load may also become increasingly time-consuming as the dataset grows, since every run processes the complete dataset again.
The key difference is that the initial load is typically a one-time operation, while the time and resource requirements of repeated full loads can continue increasing as data volumes grow.


Initial Load vs Full Load ETL: Rows Sync
In terms of Initial Load vs Full Load ETL, Initial Load can be carried out for all new records from disparate sources. On the other hand, for Full Load ETL, all the rows in source data would get synced.

Shortcomings of Incremental Data Loads
The initial full load is relatively straightforward. However, when you start taking on incremental loads, things might get more complex. Here are three of the most common problem areas:
- Schema Evolution: You need to have an idea about what happens to your existing data when a new property gets added, or an existing property is changed. Some of these changes can be quite destructive or leave data in an inconsistent state. For instance, having an idea about what transpires if your Data Warehouse starts receiving string values for a field that is expected to be an integer datatype.
- Ordering: To handle massive scale with high availability, Data Pipelines are quite often distributed systems. This means that arriving data points can take different data paths through the system, which means they can be processed in a different order than in which they were received. If data is being deleted or updated, processing in the wrong order could lead to bad data. Auditing and maintaining order are crucial for maintaining the accuracy of data.
- Monitorability: With data coming from a large number of disparate sources, failures are pretty inevitable. A few common failure scenarios are as follows:
- API credentials might expire.
- An API is down for maintenance.
- Network congestion prevents communication with an API.
- API calls are returning successfully, but do not possess any data.
- The pipeline destination is offline.
Any of these problems will probably result in data that is either wrong or incomplete. Therefore, recovering from these issues could turn out to be a massive headache.
To know more about Incremental Data Load vs Full Load ETL, check out our blog.


Conclusion
This article talks about the salient differences between Initial Load and Full Load as ETL processes for your data pipeline and explains their salient aspects to give you a better understanding.
However, as a Developer, extracting complex data from a diverse set of data sources like Databases, CRMs, Project management Tools like Jira, Streaming Services, and Marketing Platforms to your Database can seem to be quite challenging. If you are from non-technical background or are new in the game of data warehouse and analytics, Hevo can help!
Frequently Asked Questions
1. What Is the Difference Between Part Load and Full Load?
Part Load: Only a portion of the data is loaded, often incremental or specific to certain criteria.
Full Load: The entire dataset is loaded at once, typically used during the initial data migration or setup.
2. What Is a Full Load?
A full load refers to loading the complete dataset into a system without filtering or segmentation, usually during the initial data transfer.
3. What Is Initial Load Size?
Initial load size is the total amount of data transferred during the first full load process when migrating or setting up a new data system.

Share it with your connections.
-
 Share To X
-
 Share To LinkedIn
-
 Share To Facebook
-
 Copy Link


